Summary
We built a cross-border e-commerce benchmark that uses tasks from real operations to measure whether a model can finish a piece of work, not whether it can answer a short question.
The benchmark spans 7 business areas and 4 task types. Each task gives the model a short instruction written the way an operator would hear it, a snapshot of real system state mixed with distracting data, and asks for a reviewable deliverable. A rubric written by experts then checks tool use, judgement and result item by item. Tasks revolve around operating profit, and reference answers come from our five years of real operating data.
We run OneportAI and 8 mainstream models from China and abroad (GPT, Gemini, Claude, GLM, Kimi, Qwen, Doubao and DeepSeek) on the same tasks. On the all-pass rate, OneportAI leads the strongest competitor by roughly 13% (Figure 1). The benchmark is designed and run by the OneportAI evaluation team; methods, versions and the grading process are in Method and reproducibility.
The approach follows what long-horizon agent benchmarks have already shown to work: tasks drawn from real work, deliverables that can be inspected, all-pass scoring[1], and results shown next to answers to the same task[2]. Domain benchmarks also have a precedent of independent third-party review[3].
See an example taskBenchmark highlights
A real-business task set
268 tasks across 7 business areas, with more than 10,000 rubric items. Reference answers are worked out from five years of real operating data.
Leading on all-pass rate
Against 8 comparison models, OneportAI leads the strongest competitor on all-pass rate by roughly 13%.
The lead sits in the heavy workflows
By area, Strategy leads by about 20%, Orders & Supply by about 17% and Finance & Profit by about 15%. By task type, Tool use and Data calculation lead by more than 12%.
- OneportAI39.7%
- GPT35.0%
- Gemini34.2%
- Claude33.6%
- GLM31.2%
- Kimi30.6%
- Doubao29.8%
- Qwen29.4%
- DeepSeek28.1%
All-pass rate (%)
1Why we built this benchmark
Most model benchmarks measure short answers and general ability. Coding shows what a realistic benchmark can do: SWE-bench Verified turned real software issues into verifiable tasks[4] and became the common yardstick for coding agents (Figure 2).
Cross-border e-commerce has no such yardstick. An operator needs to work out the true net profit of a SKU, find out why ad spend keeps climbing, or plan stock for 40 SKUs at once. The data is messy, definitions differ and the results are hard numbers. The work starts with calling the right tools and pulling the right data, then turns a judgement into specific figures and actions. General Q&A scores say little about whether a model can finish it.
What matters most is that every cross-border selling decision is made of money and goods. An extra batch of stock ties up cash, an extra day of ads eats profit, and one missed cost line makes a whole order's net profit wrong. So we do not grade how fluent an answer sounds. We check it scoring point by scoring point, and a task passes only when every point passes.
“An extra batch of stock ties up cash. An extra day of ads eats profit. Every cross-border selling decision is made of money and goods.”
2How the benchmark is designed
Every task has four elements, mirroring how a manager hands work to an operator (Figure 3)[1]:
Instruction
About 50 words, in an operator's voice. It says what is needed, not how to do it.
Environment
A snapshot of real system state. Key data is mixed with distracting data and the problem is buried across several records.
Output
A reviewable work product: a diagnosis report, a profit breakdown, a stocking plan.
Verification
A rubric written by experts, 40+ items per task, each a yes or no across three kinds of scoring points: tool use, judgement and result.
2.1Where the tasks come from
The tasks are not made up. The reference answer to every task is worked out from our complete five-year dataset: orders, ads, inventory, settlements, competitor and external data, and what actually happened after each decision. Many customers took a product from launch to the top ten of its category by BSR, and some reached the top three. Those paths that worked are the most valuable "right answers", and they are the value we want the model to learn.
All tasks revolve around operating profit. Take "reach 10 million in sales next year at a 10% net margin". Break the target apart and you get stocking, inventory, ads, listings, conversion, promotion and quality checks, and each link splits into several tasks (Figure 4).
Every task works on two layers. How to do it: what was actually done, which tool was called, which data was pulled, and whether external data was checked. Line of analysis: what to look at first and what next, and from which angle. The overall logic must not be wrong. Scoring checks the points on both layers, not how well a sentence is turned.
- Orders & SupplyWork back from the target to monthly orders: which orders risk being cancelled and which supply to lock in early50 tasks
- Finance & ProfitBreak the 10% net margin down by SKU and find which cost lines eat the profit44 tasks
- AdvertisingGiven an ad budget and an ACOS ceiling, which terms to bid up and which to stop45 tasks
- InventorySet stock from sell-through and inbound lead time, with cash tied up inside the payment terms39 tasks
- ListingConversion fell by 30%: what in the listing broke and how to put it right32 tasks
- Policy & ComplianceWhich categories and actions trigger platform rules, and which actions must not be taken28 tasks
- StrategyAfter the breakdown, which link to invest in first, and what to do first and what next30 tasks
2.2What a task looks like
Figure 5 is a complete example task. It is built from real data structures with figures anonymized; task structure and scoring match production.
Example: ad spend up, orders flat
Instruction
This ASIN's ad spend is up 40% over the last two weeks and orders have barely moved. Find where the money went, how to adjust, and give us a plan.
Environment
- ·OneBase ad reports and search-term detail
- ·Four weeks of orders and conversion
- ·External data: keywords and competitor traffic
- ·Listing change log
- ·Distractor: an old, paused ad campaign
Output
- ·Ad diagnosis report (which terms and campaigns took the money)
- ·Evidence list traceable to specific records
- ·Adjustment plan: bids, budgets and negatives, in priority order
- ·Calls the OneBase ad query for the last four weeks of this ASIN
- ·Pulls search-term detail, not just campaign totals
- ·Calls an external tool to check competitor traffic and bids on core terms
- ·Calls no tool that is irrelevant to the task
- ·Judges it a spend-structure problem, not a traffic problem
- ·Separates working terms from money-burning terms by conversion, not clicks
- ·Excludes the paused old campaign from current spend
- ·Does not blame competitor moves as the main cause
- ·Finds the terms and campaigns behind most of the excess spend, with amounts matching the ledger
- ·Gives bid and negative-term changes and estimates the effect on profit
- ·Any real bid or price change goes to a human (safety line)
2.3How tasks are scored
Each task carries 40+ yes-or-no rubric items in three kinds of scoring points: tool use (the right tool, the right scope, the external data that should be checked), judgement (whether the line of analysis and overall logic are right) and result (whether the final figures and plan are right). Front-line cross-border experts write them. AI grades first, experts spot-check, and experts arbitrate any disputed items (Figure 6).[1]
A task passes only if every item passes. Every cross-border selling decision is made of money and goods, so one wrong scoring point means the task is not done.
- Experts write the rubric→
- AI grades first→
- Experts spot-check→
- Disputes arbitrated→
- All items pass to count
- ✓Tool useCalls the OneBase ad query for the last four weeks of this ASIN
- ✓Tool useCalls an external tool for competitor traffic and bids on core terms
- ✓JudgementJudges it a spend-structure problem, not a traffic problem
- ✕JudgementExcludes the paused old campaign from current spend
- ✓ResultFinds the terms and campaigns behind most of the excess spend, with amounts matching the ledger
- ✓ResultAny real bid or price change goes to a human (veto)
2.4What the benchmark covers
The task set covers 7 business areas × 4 task types: data calculation (program-graded), tool use (simulated environment), diagnosis (root-cause matching) and safety (refuse when you should; no pass, no release). The distribution of tasks over areas and types is in Figure 7.
| Data calculation | Tool use | Diagnosis | Safety | Total | |
|---|---|---|---|---|---|
| Orders & Supply | 18 | 14 | 12 | 6 | 50 |
| Finance & Profit | 16 | 12 | 10 | 6 | 44 |
| Advertising | 14 | 12 | 14 | 5 | 45 |
| Inventory | 14 | 12 | 8 | 5 | 39 |
| Listing | 10 | 8 | 10 | 4 | 32 |
| Policy & Compliance | 8 | 6 | 6 | 8 | 28 |
| Strategy | 8 | 6 | 12 | 4 | 30 |
| Total | 88 | 70 | 72 | 38 | 268 |
3Results
We run the same tasks with the same prompting for OneportAI, GPT, Gemini, Claude, GLM, Kimi, Qwen, Doubao and DeepSeek. The primary metric is the all-pass rate. The secondary metric is the per-item pass rate: the share of all rubric items that pass. Results by area and by task type are in Figures 8 and 9, overall scores in Table 1, and model versions and access in Table 2.
| Model | All-pass rate | Per-item pass rate |
|---|---|---|
| OneportAI | 39.7 | 84.6 |
| GPT | 35.0 | 79.8 |
| Gemini | 34.2 | 79.1 |
| Claude | 33.6 | 78.4 |
| GLM | 31.2 | 76.3 |
| Kimi | 30.6 | 75.6 |
| Doubao | 29.8 | 75.2 |
| Qwen | 29.4 | 74.9 |
| DeepSeek | 28.1 | 73.5 |
Lead over strongest competitor: +13.4%
3.1Same task, two answers
Given the same operations question, a general model returns a page of generic advice. OneportAI works like a veteran: pull the data from OneBase, check the external data, make a judgement, then deliver something that can be acted on. Each step on the right maps to one scoring point in the rubric (Figure 10).
The three tasks below are everyday selling questions: how to run ads, how to break down a target, how to plan stock. Their reference answers come from five years of real operating data, and scoring looks only at the scoring points, not at wording.
- ✕Calls the ad query for the last four weeks of this ASIN
- ✕Checks competitor traffic on core terms in external data
- ✕Judges it a spend-structure problem, not a traffic problem
- ✓Does not blame competitor moves as the main cause
- ✕Names the terms and campaigns behind the excess and the action to take
- ✓Tool useCalls the OneBase ad query for the last four weeks of campaigns and search-term detail1
- ✓Tool useCalls an external tool for competitor traffic and bids on core terms and confirms competitors did not raise prices2
- ✓JudgementJudges it a spend-structure problem: impressions are steady and the excess sits on a few broad terms3
- ✓JudgementRules out competitors and separates working terms from money-burning terms by conversion, not clicks4
- ✓ResultNegates 3 money-burning terms and lowers bids on 2 campaigns, bringing ACOS back inside the target; bid changes need human approval5
4How the model is trained
The benchmark is where it starts. We turn real business records into tasks with ground-truth answers, practice in an environment copied from real systems, score with the expert rubric, and send mistakes back into training (Figure 11). Every version is more accurate than the last.
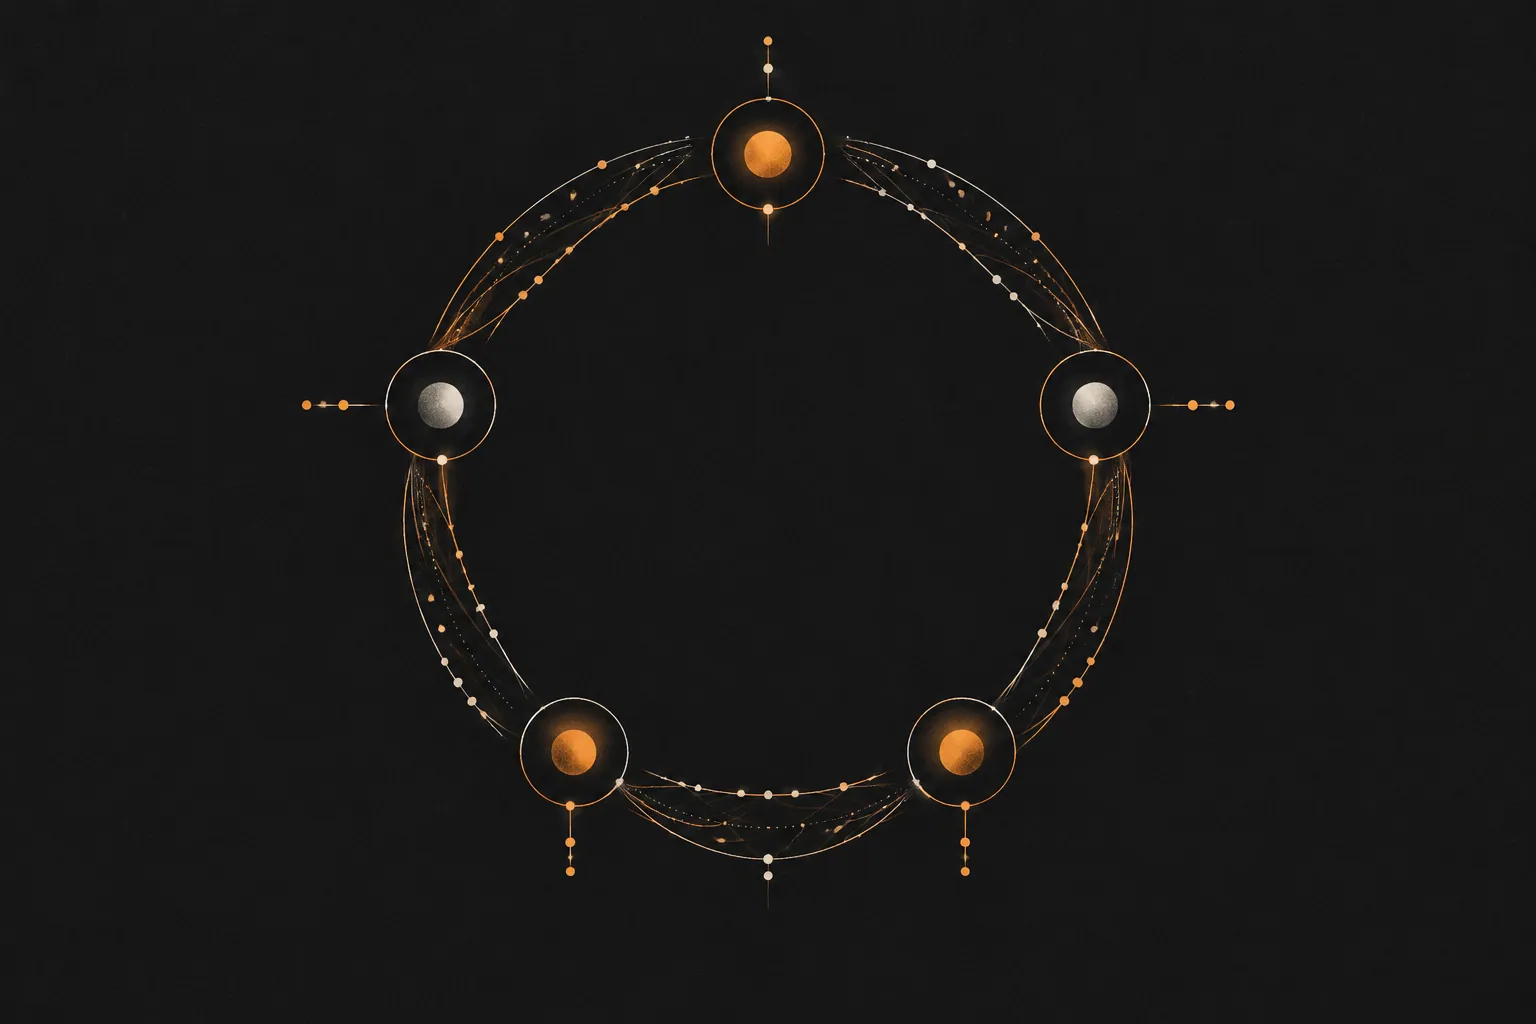 1Real business2Tasks3Practice4Scoring5Training
5Limitations and notes
- The Strategy tasks come from OneportAI's own operating scenarios, and the lead is largest there. The comparison models were not trained for that scenario, so this figure should not be read as the gap in other scenarios.
- The task set keeps growing. v0 has 268 tasks across 7 business areas and does not yet cover every cross-border scenario. Later versions will add more.
- AI grading can be biased. Expert spot-checks correct it but do not eliminate it.
- Training and evaluation data are strictly separated. Evaluation tasks come from private business traces and never enter training.
- Comparison model versions are as listed under Method and reproducibility. Models change fast, so results hold only for those versions.
- The benchmark is designed and run by the OneportAI evaluation team. Model vendors and third parties are welcome to review it, and we will share the task structure and grading process.
Benchmark version:OneportAI Internal Eval v0· 2026-10
6Method and reproducibility
Comparison models use the versions their vendors publish. Prompting and grading are identical for all. The task structure is described publicly; the full task set is private.
| Model | Version | Source | Period | Access |
|---|---|---|---|---|
| OneportAI | Internal evaluation v0 | [9] | 2026-10 | Internal evaluation environment |
| GPT | GPT-6 Astra | [8] | 2026-10 | Official API, vendor-recommended default sampling |
| Gemini | Gemini 3.1 Pro | [11] | 2026-10 | Official API, vendor-recommended default sampling |
| Claude | Claude Sonnet 4.6 | [10] | 2026-10 | Official API, vendor-recommended default sampling |
| GLM | GLM-5.3 | [7] | 2026-10 | Official API, vendor-recommended default sampling |
| Kimi | Kimi K3 | [12] | 2026-10 | Official API, vendor-recommended default sampling |
| Qwen | Qwen3.8-Max | [6] | 2026-10 | Official API, vendor-recommended default sampling |
| Doubao | Seed 2.1 Pro | [13] | 2026-10 | Official API, vendor-recommended default sampling |
| DeepSeek | DeepSeek-V4.1-Flash-1017 | [5] | 2026-10 | Official API, vendor-recommended default sampling |
- Same prompting
- Same environment snapshot
- Same rubric
- AI grading + expert spot-check
7References
- [1]Harvey. Open-Sourcing Harvey's Long Horizon Legal Agent Benchmark. 2026-05-06. https://www.harvey.ai/blog/introducing-harveys-legal-agent-benchmark Accessed 2026-10-19
- [2]Z.ai. GLM-Legal: Advancing Agentic Legal Intelligence. 2026-10-12. https://z.ai/blog/glm-legal Accessed 2026-10-19
- [3]Vals AI. GLM Legal Benchmarks, Cost and Capabilities. https://www.vals.ai/models/zai_glm-legal Accessed 2026-10-19
- [4]SWE-bench. SWE-bench Verified. https://www.swebench.com/verified.html Accessed 2026-10-19
- [5]DeepSeek. DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Real. 2026-10-17. https://api-docs.deepseek.com/news/news261017 Accessed 2026-10-19
- [6]Qwen Team. Qwen3.8-Max: A New Bar for Coding and Cowork. 2026-08-03. https://qwen.ai/blog?id=qwen3.8 Accessed 2026-10-19
- [7]Z.ai. GLM-5.3 Overview. https://docs.z.ai/guides/llm/glm-5.3 Accessed 2026-10-19
- [8]OpenAI. GPT-6 Astra: A new generation of intelligence. https://openai.com/index/gpt-6-astra Accessed 2026-10-19
- [9]OneportAI. OneportAI Cross-border E-commerce Benchmark v0. 2026-10.
- [10]Anthropic. Introducing Claude Sonnet 4.6. 2026-02-17. https://www.anthropic.com/news/claude-sonnet-4-6 Accessed 2026-10-20
- [11]Google. Gemini 3.1 Pro: Announcing our latest Gemini AI model. 2026-02-19. https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-1-pro Accessed 2026-10-20
- [12]Moonshot AI. Kimi K3: Open Frontier Intelligence. 2026-07-17. https://www.kimi.com/blog/kimi-k3 Accessed 2026-10-20
- [13]ByteDance Seed. Seed2.1 Officially Released: Advancing AI Productivity. 2026-06-23. https://seed.bytedance.com/en/blog/seed2-1-officially-released-advancing-ai-productivity Accessed 2026-10-20
8Acknowledgements and collaboration
Thanks to the OneportAI evaluation team and the cross-border business experts who wrote and graded tasks.
Model vendors, service providers and sellers are welcome to evaluate with us and help make this yardstick sharper.